Welcome to Code Forum!

Join a community that supports you and your coding journey from day one. We strive to be a friendly, supportive community that empowers everyone to be better developers. By registering with us, you'll be able to discuss, share and private message with other members of our community.

SignUp Now!
  • Guest, before posting your code please take these rules into consideration:
    • It is required to use our BBCode feature to display your code. While within the editor click < / > or >_ and place your code within the BB Code prompt. This helps others with finding a solution by making it easier to read and easier to copy.
    • You can also use markdown to share your code. When using markdown your code will be automatically converted to BBCode. For help with markdown check out the markdown guide.
    • Don't share a wall of code. All we want is the problem area, the code related to your issue.
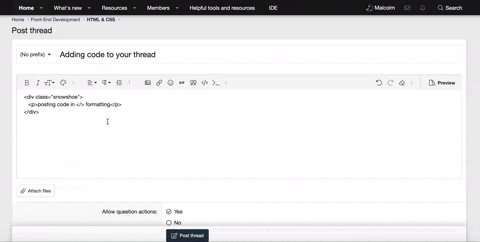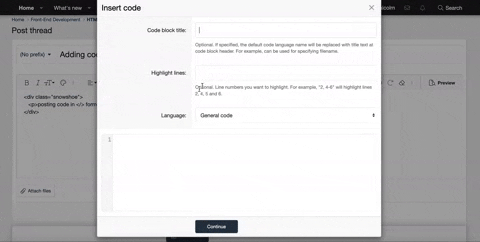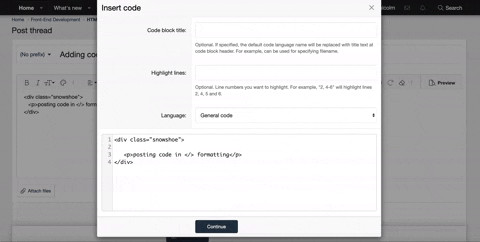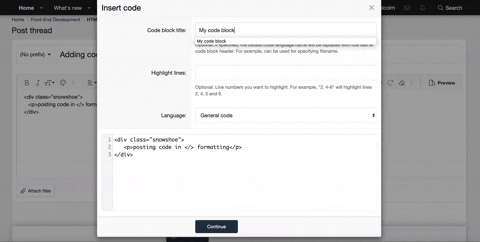
    GIF shows where to locate </> in the thread and or post editor toolbar.
    To learn more about how to use our BBCode feature, review our "How to post your code into threads" here.

    Thank you, Code Forum.

HTML & CSS Help getting past dropdown list barrier on website

seann7777

New Coder
I am trying to get a view of client names from an organization's website. To give some background, at the registration page of this website, there is a "choose your organization" step. It prompts the user to "Start typing your organization and select it from the list. If it does not appear, select 'Other'." It requires 3 letters to be typed out before a dropdown list appears (which is limited to a certain number of organizations on the list). Is there any way to get past this?
 
Lets keep the chat on here as this one is intresting and may help someone else. So what you are after is quite simple and i have already coded something 😀 Just need to work out how on earth we get the AAA,AAB,AAC to work and then i can upload my code 😀
 
Okay and we are done 😀 So what i did was find the Get Request function, this is what that search function was calling, i then sent the 17500 ABC variations, took the company names, made sure its not in the array all ready and added it if it was not 🙂, I also used Concurrent connections or we would have been there all day doing them one by one, YES before someone moans at me its not the best way of doing things and not website considerate but for such a short period of time it will not effect the servers much 🙂

Python:
import requests
import concurrent.futures

FullNames = []
FullSearchTerms = []
letters = list('ABCDEFGHIJKLMNOPQRSTUVWXYZ')

def scrape_url(value):
    cookies = {
        'ADC_CONN_539B3595F4E': '5910D6BA7A24B741984F93F5A3253EAB39295619D65E4414FB8A8FEB13B5CE101F430747F06AD633',
        '__RequestVerificationToken': 'ZG2SflklTjJsbQeUHhBTrsnuRGVTeYPZdF1kyXUSiqH7AqkzKQ_vaOeWAu8feyqPBKd6d-Izfx-YkDhVDkuNfmyvbfM1',
        'ADC_REQ_2E94AF76E7': 'AEF437AEE500E740176EBD6E68CA5E99C839A7DE6B76C8C3CDF07E3520B6562E44FF1DA259EDFF4D',
        '_ga': 'GA1.2.1705573474.1637113061',
        '_gid': 'GA1.2.960381828.1637113061',
        '_gat': '1',
    }

    headers = {
        'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64; rv:94.0) Gecko/20100101 Firefox/94.0',
        'Accept': 'application/json, text/javascript, */*; q=0.01',
        'Accept-Language': 'en-GB,en;q=0.5',
        'X-NewRelic-ID': 'VQ4PUFNVCBABVVNWBwUBUFE=',
        'X-Requested-With': 'XMLHttpRequest',
        'Connection': 'keep-alive',
        'Referer': 'https://members.healthadvocate.com/Account/OrganizationSearch',
        'Sec-Fetch-Dest': 'empty',
        'Sec-Fetch-Mode': 'cors',
        'Sec-Fetch-Site': 'same-origin',
    }

    params = (
        ('search', value),
    )

    response = requests.get('https://members.healthadvocate.com/Account/GetClients', headers=headers, params=params,cookies=cookies)
    data = response.json()
    for data2 in data:
        if data2['Name'] not in FullNames:
            FullNames.append(data2['Name'])

for a in letters:
    for b in letters:
        for c in letters:
            Got = (a+b+c)
            FullSearchTerms.append(Got)
            Got = ""


with concurrent.futures.ThreadPoolExecutor(max_workers=100) as executor:
   executor.map(scrape_url,FullSearchTerms)

print(FullNames)
print(len(FullNames))


i found 2130 companys and the text doc attached is the print out of them found 🙂

Hope this helps 🙂
 

Attachments

Okay and we are done 😀 So what i did was find the Get Request function, this is what that search function was calling, i then sent the 17500 ABC variations, took the company names, made sure its not in the array all ready and added it if it was not 🙂, I also used Concurrent connections or we would have been there all day doing them one by one, YES before someone moans at me its not the best way of doing things and not website considerate but for such a short period of time it will not effect the servers much 🙂

Python:
import requests
import concurrent.futures

FullNames = []
FullSearchTerms = []
letters = list('ABCDEFGHIJKLMNOPQRSTUVWXYZ')

def scrape_url(value):
    cookies = {
        'ADC_CONN_539B3595F4E': '5910D6BA7A24B741984F93F5A3253EAB39295619D65E4414FB8A8FEB13B5CE101F430747F06AD633',
        '__RequestVerificationToken': 'ZG2SflklTjJsbQeUHhBTrsnuRGVTeYPZdF1kyXUSiqH7AqkzKQ_vaOeWAu8feyqPBKd6d-Izfx-YkDhVDkuNfmyvbfM1',
        'ADC_REQ_2E94AF76E7': 'AEF437AEE500E740176EBD6E68CA5E99C839A7DE6B76C8C3CDF07E3520B6562E44FF1DA259EDFF4D',
        '_ga': 'GA1.2.1705573474.1637113061',
        '_gid': 'GA1.2.960381828.1637113061',
        '_gat': '1',
    }

    headers = {
        'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64; rv:94.0) Gecko/20100101 Firefox/94.0',
        'Accept': 'application/json, text/javascript, */*; q=0.01',
        'Accept-Language': 'en-GB,en;q=0.5',
        'X-NewRelic-ID': 'VQ4PUFNVCBABVVNWBwUBUFE=',
        'X-Requested-With': 'XMLHttpRequest',
        'Connection': 'keep-alive',
        'Referer': 'https://members.healthadvocate.com/Account/OrganizationSearch',
        'Sec-Fetch-Dest': 'empty',
        'Sec-Fetch-Mode': 'cors',
        'Sec-Fetch-Site': 'same-origin',
    }

    params = (
        ('search', value),
    )

    response = requests.get('https://members.healthadvocate.com/Account/GetClients', headers=headers, params=params,cookies=cookies)
    data = response.json()
    for data2 in data:
        if data2['Name'] not in FullNames:
            FullNames.append(data2['Name'])

for a in letters:
    for b in letters:
        for c in letters:
            Got = (a+b+c)
            FullSearchTerms.append(Got)
            Got = ""


with concurrent.futures.ThreadPoolExecutor(max_workers=100) as executor:
   executor.map(scrape_url,FullSearchTerms)

print(FullNames)
print(len(FullNames))


i found 2130 companys and the text doc attached is the print out of them found 🙂

Hope this helps 🙂
Simon,

This is awesome. Thank you so much for doing this for me - it inspires me to learn more! I can't express how cool it is that you helped me with this... i thought it was a shot in the dark. Very kind of you. I am glad that you saw it as an interesting task. Hopefully it was something new for you, even though it was relatively simple.

Thanks again,
Sean
 

Latest posts

Buy us a coffee!

Buy me a coffee.
Back
Top Bottom