I am using gensim word2vec and trying to get train a model so that aIget good similarity scores between two words. However if I use this to find the similarity between two words such as hot and cold I find that they have a high similarity, and similarity for other word pairs that should generally be different. Is there a way to train the model to get good similarity scores?
Welcome to Code Forum!
Join a community that supports you and your coding journey from day one. We strive to be a friendly, supportive community that empowers everyone to be better developers. By registering with us, you'll be able to discuss, share and private message with other members of our community.
-
Guest, before posting your code please take these rules into consideration:
- It is required to use our BBCode feature to display your code. While within the editor click < / > or >_ and place your code within the BB Code prompt. This helps others with finding a solution by making it easier to read and easier to copy.
- You can also use markdown to share your code. When using markdown your code will be automatically converted to BBCode. For help with markdown check out the markdown guide.
- Don't share a wall of code. All we want is the problem area, the code related to your issue.
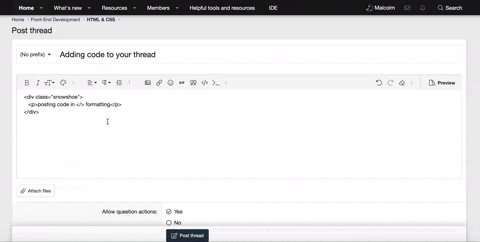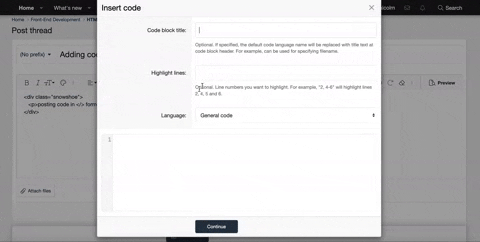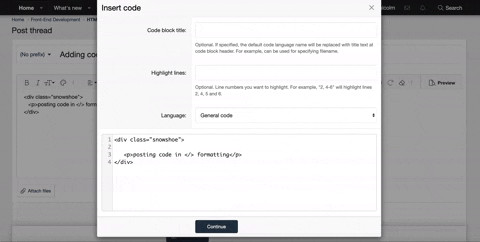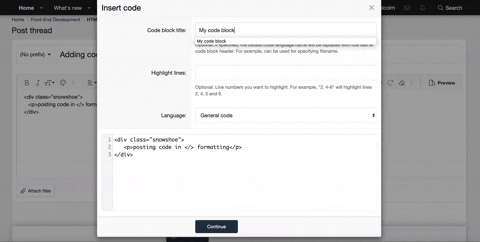
To learn more about how to use our BBCode feature, review our "How to post your code into threads" here.
Thank you, Code Forum.
Python Gensim word2vec how to train model to get good similarity scores
- Thread starter thidmir
- Start date
New Threads
-
What Should Players Check Before Trying Online Wheel-of-Fortune Games?
- Started by kemiy
- Replies: 2
-
-
-
What Should I Look for in a Link-Building Service for Restricted Industries?
- Started by kemiy
- Replies: 2
-

Share this page
Buy us a coffee!